FastAPI on EC2 ARM64 with Caddy reverse proxy and atomic Redis token validation.
Sensitive client prompts and responses are computed strictly on private local hardware.
Private Ubuntu ThinkPad server operates over outbound Cloudflare Tunnel sockets.
Eliminating the Dilemma Between Cloud Invoices and Local Chaos
Running a local open-weights LLM is straightforward. Engineering an enterprise-grade developer gateway around that model — with zero data leakage, sub-25ms routing, and multi-tenant rate limiting — is the true systems challenge.
Convenient setup, but recurring per-token SaaS subscriptions scale uncontrollably as concurrency grows, while sensitive internal data is perpetually transmitted across third-party infrastructure.
Raw inference engines (Ollama, vLLM) lack developer portals, API key generation, SHA-256 validation, sliding-window rate limiters, and audit logging — crashing easily under concurrent production load.
Three Strictly Decoupled Production Tiers
Engineered for strict separation of concerns between public identity management and secure private model computation:
Developer Web Dashboard
Hosted on AWS Amplify with global CloudFront CDN edge distribution. Features Next.js 15 App Router, Google OAuth 2.0, API key generation, and real-time usage telemetry charts.
High-Throughput Gateway
Dockerized FastAPI container running on AWS EC2 ARM64 with Caddy reverse proxy. Enforces cryptographic SHA-256 API key verification, atomic Redis sliding-window quotas, and monthly token limits.
Edge Inference Engine
Physical Linux server operating on a dedicated Ubuntu ThinkPad. Multi-threaded AVX2 CPU inference via llama.cpp server, exposed strictly through an outbound Cloudflare Tunnel with zero open inbound ports.
Production Engineering Tooling
Every tool in the stack was selected for sub-second execution, strict zero-trust security, and zero cloud subscription invoices:
Next.js 15.1
Hosted on AWS Amplify with CloudFront edge caching, powering dashboard.aroonkumar.me.
FastAPI
High-throughput async gateway on AWS EC2 ARM64 handling /v1/chat/completions and SSE streams.
AWS EC2 & Amplify
Dockerized container deployment with CI/CD pipeline, ECR registry, and global Amplify hosting.
Cloudflare Tunnel
Persistent outbound multiplexed tunnel from ThinkPad to Edge with zero open public router ports.
llama.cpp
Multi-threaded C++ inference server running locally on Ubuntu ThinkPad with real-time SSE chunks.
PostgreSQL 15
Stores users, Argon2id passwords, SHA-256 API key hashes, quotas, and granular token telemetry.
Redis 7 In-Memory
Atomic per-developer token rate limiting (10 req/min) to prevent inference hardware thrashing.
Ubuntu Linux
Physical dedicated edge server with UFW firewall, memory/swap tuning, and managed services.
Docker Container
Hermetic container bundling FastAPI and dependencies for predictable, reproducible cloud hosting.
Python 3.11
Core runtime executing gateway logic, request validation, cryptographic hashing, and DB pooling.
TypeScript
Guarantees end-to-end type safety across the entire dashboard portal, API models, and UI state.
Caddy Server
Reverse proxy on EC2 handling HTTP/2 TLS handshake, upstream routing, and connection buffering.
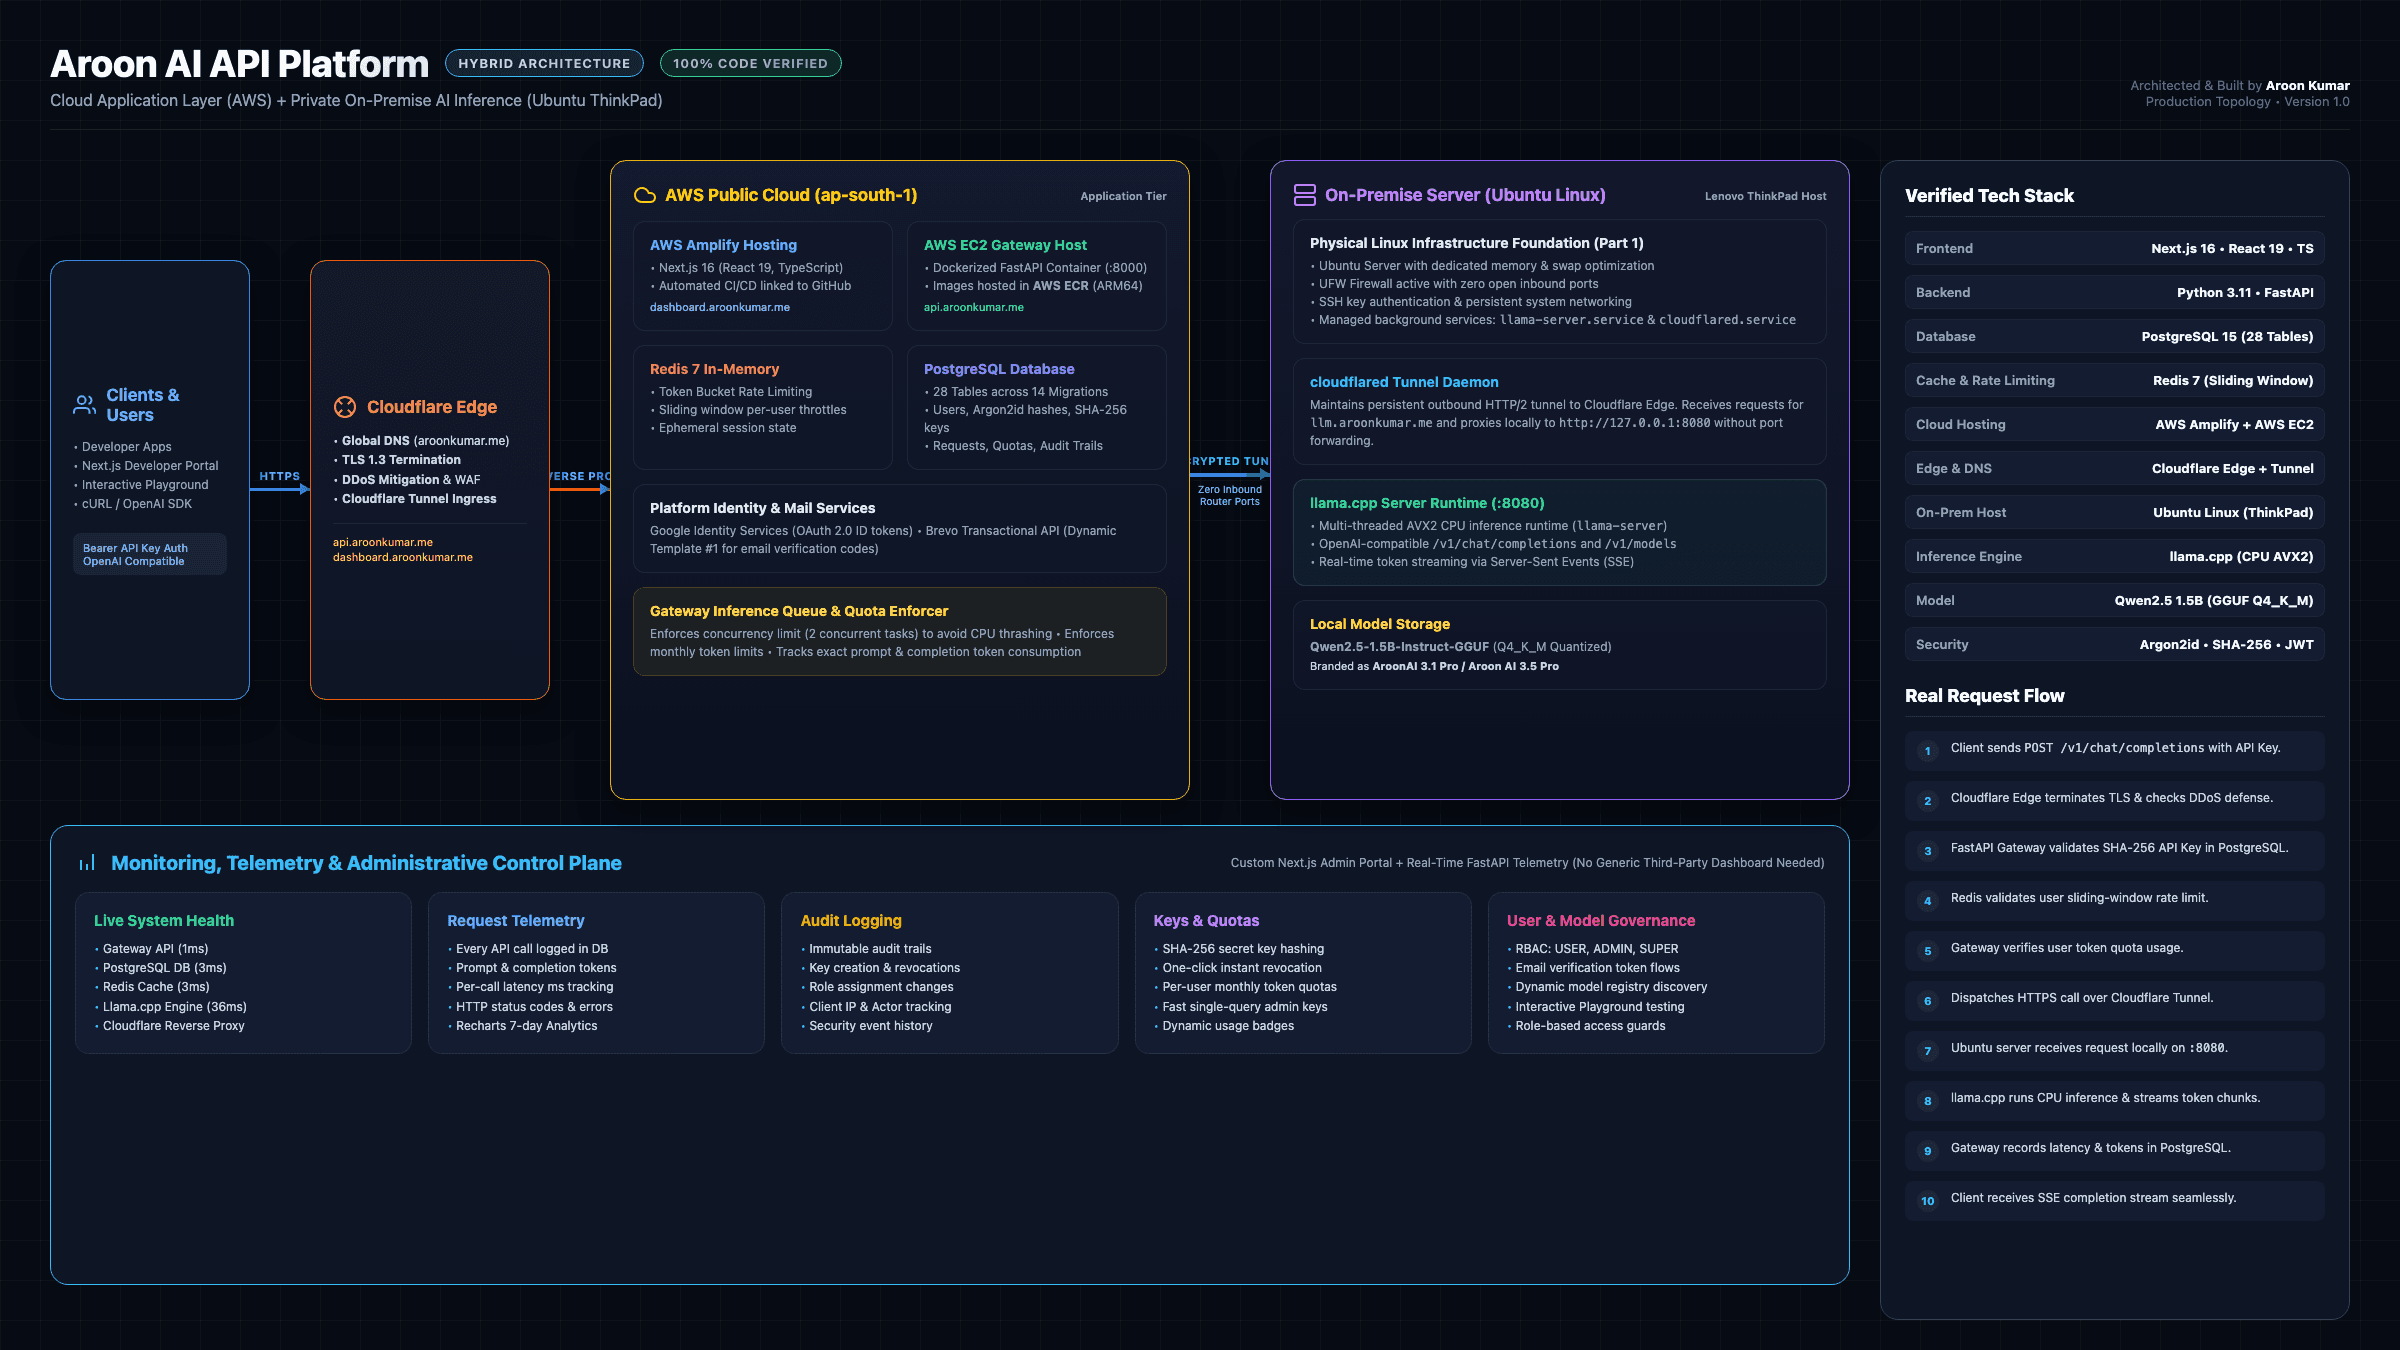
Verified Production Topology Blueprint
Inspect the complete 2,400px architecture diagram covering AWS Cloud, Cloudflare Edge, and On-Premises ThinkPad inference:
Interactive Code Workbench
Drop-in compatibility with the official OpenAI SDK, pure Python urllib, Node.js fetch, and terminal cURL:
# 1. Python (Official OpenAI SDK — Drop-in Base URL)
from openai import OpenAI

# ⚠️ Point base_url to Aroon AI Gateway (Zero data leaves private host)
client = OpenAI(
    api_key="aroon_sk_YOUR_API_KEY",
    base_url="https://api.aroonkumar.me/v1",
)

# Streaming Completion (Real-time Word-by-Word SSE Generation)
stream = client.chat.completions.create(
    model="aroonai-3.1-pro",
    messages=[
        {"role": "system", "content": "You are a concise, helpful engineering assistant."},
        {"role": "user", "content": "Explain hybrid cloud AI gateway architecture."}
    ],
    stream=True,
    temperature=0.7,
)

for chunk in stream:
    if chunk.choices and chunk.choices[0].delta.content:
        print(chunk.choices[0].delta.content, end="", flush=True)
print()10-Step End-to-End Request Journey
Click any step to trace the journey of an AI chat completion from client dispatch to streamed tokens:
Client Bearer Request
Client sends HTTP POST to /v1/chat/completions with Bearer aroon_sk_... API key.
Cloudflare Edge Defense
Cloudflare terminates TLS, handles DDoS scrubbing, and enforces edge WAF inspection.
Cryptographic SHA-256 Auth
FastAPI gateway computes SHA-256 hash of API key and performs single-query Postgres lookup.
Atomic Redis Rate Limiting
Atomic Redis Lua scripts verify sliding-window quota (10 req/min) to prevent CPU queue thrashing.
Monthly Token Quota Check
Gateway checks developer prompt + completion token consumption against monthly tier cap.
Outbound Tunnel Dispatch
Request proxied over persistent outbound HTTP/2 Cloudflare Tunnel with zero open router ports.
Local Host Ingress (:8080)
Local cloudflared daemon receives packet and forwards strictly to http://127.0.0.1:8080.
AVX2 CPU Engine Inference
llama.cpp server executes quantized Qwen2.5-1.5B weights using multi-threaded AVX2 instructions.
Database Telemetry Logging
Latency (ms), prompt tokens, completion tokens, and client IP asynchronously logged to PostgreSQL.
Real-time SSE Streaming
Client receives token-by-token Server-Sent Events (SSE) with standard [DONE] termination flag.
Want to deploy private, sovereign AI infrastructure?
We design and deploy self-hosted developer gateways with OpenAI SDK drop-in compatibility, zero cloud token bills, and complete on-premises data sovereignty.